AI & technology
Synthetic respondents & data
35 indexed claims · 15 guests · peaked 2026-Q2
Overview
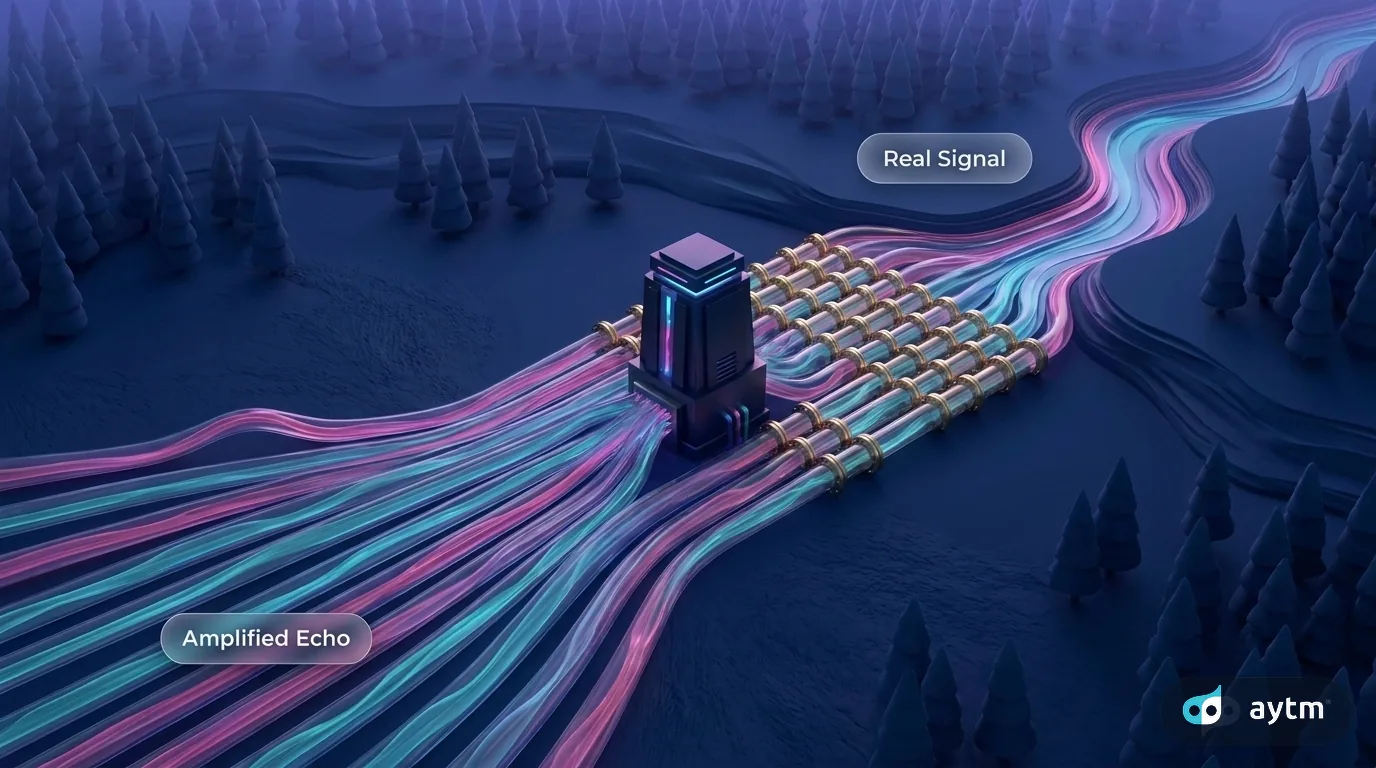
Few topics in market research cleave practitioners as sharply as synthetic data — and the definitional problem is half the fight. Across these podcast episodes, methods ranging from statistically grounded generative models to LLM-fabricated survey rows all travel under the same label. Skeptics like David Evans ('research theater') and Don DeVeaux ('hollows out the discipline') draw hard lines against AI-fabricated respondents; Jason Cohen, who builds synthetic tools for a living, draws the same line but in a very different place. The pragmatic middle — Andrew Embry at Eli Lilly, Kate O'Keeffe at Heatseeker — argues that synthetics earn their keep when matched to the right risk level and anchored in real first-party data. The deeper danger: training synthetics on survey panels may now mean training on bot-generated data, making the correlation promise circular before it even starts.
From the corpus
- Synthetic data is not a current fit for forward-looking innovation work: it is a model of past behavior, not real current consumer behavior, and it cannot predict the next big trend — for flavor foresight she must instead watch away-from-home channels, restaurants, and chefs and track how those signals trickle down to CPG. — Kerry-Ellen Schwartz, Ep. 63 ·
cl-kerry-ellen-schwartz-014 - A plausible near-future model of synthetic data is not LLM-generated mock respondents but AI assistants (Siris) acting as synthetic interpreters of real human telemetry — querying our assistants becomes more reliable than querying us directly, because they will know our likely behavior better than we can articulate it. — Lev Mazin, Ep. 24 ·
cl-lev-solo-016 - Synthetic or simulated respondent data in pharma is not yet trustworthy for primary research decisions; the bar for adoption should be a properly controlled side-by-side comparison — same survey design, same questions, real vs. synthetic participants, with the training provenance of the synthetic sample disclosed. — Shawn McKenna, Ep. 9 ·
cl-shawn-mckenna-010 - Because synthetic data is built on historical models, relying on it means perpetually replicating the past and cannot project drastic, unforeseen change driven by economic, political, or natural-disaster forces — COVID is the canonical example of consumer behavior no model could have predicted. — Kerry-Ellen Schwartz, Ep. 63 ·
cl-kerry-ellen-schwartz-013 - The signal that an AI vendor tool truly adds value is that it speeds up the analysis of real data; the warning sign is AI personas and synthetic respondents replacing real people, where it is unclear whether anything is actually saved or whether the answers can be trusted at all. — Kerry-Ellen Schwartz, Ep. 63 ·
cl-kerry-ellen-schwartz-017 - Synthetic audiences trained on survey data inherit the foundational flaw of surveys — they are modeling self-reported rather than actual behavior; the widespread industry claim of 80–95% correlation between synthetics and surveys proves only that both are wrong in the same way. — Kate O'Keeffe, Ep. 55 ·
cl-kate-okeeffe-010 - Inflating an N=100 dataset to half a million synthetic rows provides no value if the original survey didn't get the answers it needed; the value of generative methods is conditional ability — looking into populations or scenarios you couldn't survey — not row volume. — Jason Cohen, Ep. 43 ·
cl-jason-cohen-018 - Researchers will adopt synthetic data when it can be demonstrated with 95%+ confidence that synthetic results replicate a real-person study — but before that proof exists, claiming synthetic data works is not credible; researchers want the mechanics, not the promise. — Michael Nevski, Ep. 26 ·
cl-michael-nevski-018
Contributing guests
Episodes in Synthetic respondents & data
- From insights to foresights: predicting what consumers will need next with Kerry-Ellen Schwartz — Ep. 63 · Jun 16, 2026
- Closing the say-do gap: what live experiments reveal that surveys miss with Kate O'Keeffe — Ep. 55 · Apr 21, 2026
- How causal AI is revolutionizing consumer and market research with Jason Cohen — Ep. 43 · Jan 20, 2026
- The Gig Economy, Affluent Consumers, and What They Mean for Brands — Ep. 26 · Sep 16, 2025
- Scaling Consumer Insights: Design Thinking, Empathy, Tech & Analytics in Action — Ep. 24 · Sep 2, 2025
- The Strategic Heart of Pharma Research with Shawn McKenna — Ep. 9 · May 20, 2025